Practical 9 Data visualisation
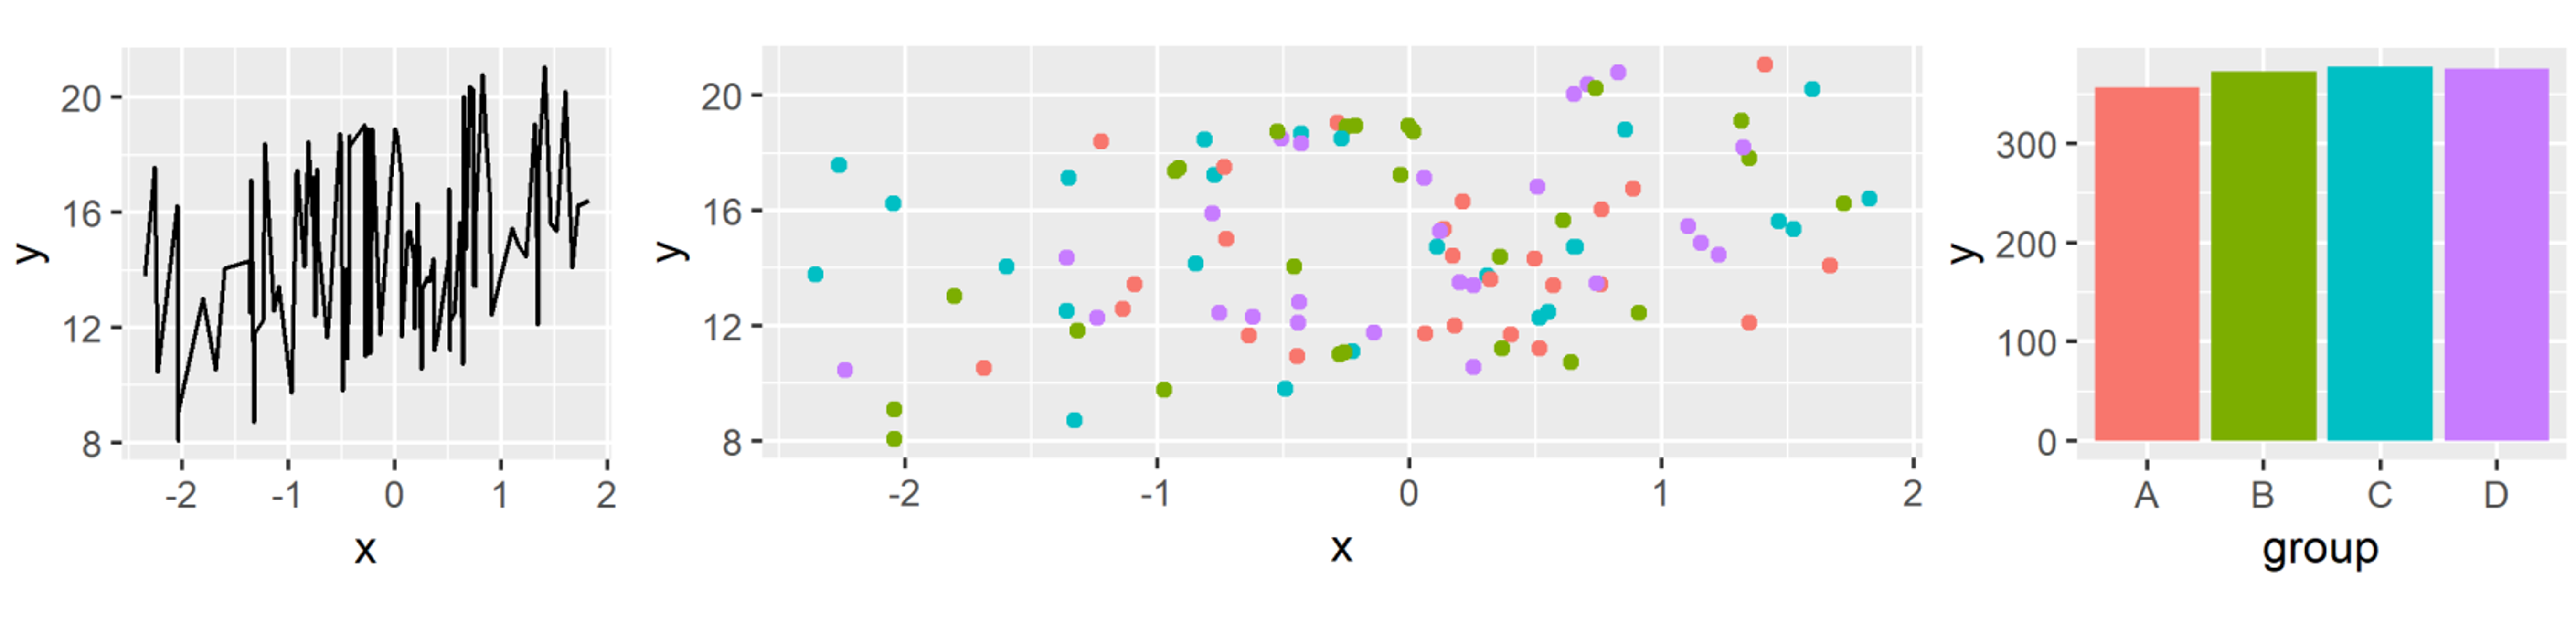
In this practical, you will cover some essential elements of presenting data graphically. You will learn two ways of making graphs in R: base R graphics, and the ggplot2 package (part of the tidyverse). For each type of plot we first show a quick base R version, and then a polished ggplot2 version.
All R graphics functions come with default settings that you can override to achieve your own design. In other words, graphs can be customised to suit the style of the particular assignment, magazine, or journal.
The two approaches work very differently:
- Base R graphics are built by drawing a plot, and then adding to it with separate function calls (a line here, some text there). You are in control of every detail, but it can take a lot of code.
ggplot2uses the grammar of graphics. You describe the plot by mapping variables in a data frame onto features of the graph (position, colour, size) and then add layers, scales and themes with+. Complicated graphs, such as the same plot repeated for each group in the data, take very little code.
So which should you use? ggplot2 is good for quick looks at your data as well as for polished figures, and many R users have moved away from base R graphics altogether. Base R graphics still have their place for specific, highly customised challenges, and it is worth knowing how they work: many functions (for example the plot() of the model diagnostics that you make with the DHARMa package) still produce base R graphics. Throughout the prac, notice what each approach makes easy and what it makes hard.
Finally, in this prac we will make plots from several datasets: data on fertilisation success in a marine invertebrate, data on bird richness in fragmented habitat, and data on beetle counts.
First, load the packages we will use. If R says a package is not found, install it first (for example: install.packages("patchwork")).
library(ggplot2)     ## Plotting
library(dplyr)       ## Summarising data
library(patchwork)   ## Combining ggplots into one figure
9.1 Histograms
You should all be familiar with histograms by now. A histogram summarises a quantitative variable. It displays the sample frequency distribution of the variable.
Histograms visually summarize discrete (e.g. counts) or continuous (e.g. tree diameter) variables by calculating how many observations fall within different intervals (bins) of the data. So far we have used them to examine the distributions of model residuals when checking if our linear models meet the assumption of "normally distributed errors". To demonstrate how to make histograms in R we will first use data on fertilisation success.
Fertilisation data An experiment was designed to test the effects of copper concentration (\(mg/L\)) and sperm concentration on fertilisation success in the free-spawning marine invertebrate, Galeolaria caespitosa. The data are available in the file: preloaded_data_1.csv in the "Data" folder of our CONS7008 R project.
Raw data are the number of eggs fertilized per 100. There are two additional variables, copper_concentration and sperm_concentration, have a look at these (one way is the head function) to familiarise yourself with the data.
9.1.1 Histograms in base R
The following code displays the histogram of fertilisation success in our sample.
What do the various vertical rectangles represent?
The width is the interval ("bin") of a variable.
The height is how often the variable fell within that interval.
9.1.1.1 Break points and labels
The break points along the horizontal axis that define the beginning and end of the rectangles are called "breaks", and the spaces between them are called "bins". Setting the breaks is the same as setting the bin-width, and it can have a dramatic effect upon the appearance of the histogram. We can also set the colour and the axis labels. Note that main = "" removes the default title: figures in reports and papers have captions rather than titles, so you will usually not want one.
hist(preloaded_data_1$fertilisation_success, breaks = seq(0, 100, by = 20))   ## Fewer bins

## What did seq do? Try intervals of 10:
seq(0, 100, by = 10)

## Smaller bins, a colour, and axis labels
hist(preloaded_data_1$fertilisation_success, breaks = seq(0, 100, by = 10), col = "grey",
     main = "", xlab = "Fertilisation success (eggs fertilised per 100)", ylab = "Frequency")
NB: For a full list of colours, type colors(). You can also use hex codes; for example, col="#000000" gives black. Sites such as coolors.co help you find nice colour schemes.
Base R lets you go much further: you can draw over the finished graph to add text, axes and curves, or put several graphs on one page with par(mfrow = ...). This gives you total control, but it takes a lot of code. Next we see how ggplot2 handles the same job.
9.1.2 Histograms in ggplot2
In ggplot2 we start by telling R which data frame to use, and which variable to put on the x-axis. This is done with ggplot(data, aes(x = ...)), where aes() stands for "aesthetics", the mapping from variables to features of the graph. We then add a layer that draws the histogram using +.
ggplot(preloaded_data_1, aes(x = fertilisation_success)) +
  geom_histogram()   ## Basic (default) histogram
R prints a message about bins = 30. The default is rarely a good choice, so as with base R we should set the bin width ourselves. Here binwidth = 10 makes bins 10 wide and boundary = 0 makes one bin start at 0, which gives the same bins as breaks = seq(0, 100, by = 10) in base R.
ggplot(preloaded_data_1, aes(x = fertilisation_success)) +
  geom_histogram(binwidth = 10, boundary = 0)
Now let's polish it. Colours are set inside the geom_: fill is the inside of the bars and colour is the outline. Labels are set with labs(), and theme_classic() gives a clean look suitable for most reports.
ggplot(preloaded_data_1, aes(x = fertilisation_success)) +
  geom_histogram(binwidth = 10, boundary = 0, fill = "grey70", colour = "black") +
  labs(x = "Fertilisation success (eggs fertilised per 100)",
       y = "Frequency") +
  theme_classic(base_size = 14)
What is the difference between fill and colour? What happens if you set fill = "pink" and colour = "blue"?
fill colours the inside of the bars and colour colours the outline.Pink bars with a blue outline.
9.1.2.1 Adding a curve to a ggplot
A common addition to a histogram is a normal curve with the same mean and standard deviation as the sample, to help judge whether the data look normally distributed. We ask for the histogram to be drawn on the density scale instead of counts (aes(y = after_stat(density))), so that it is on the same scale as the curve, and then add the curve with stat_function(). Note that the y-axis is now density, not frequency.
## Calculate the sample mean and standard deviation
av <- mean(preloaded_data_1$fertilisation_success)
stdev <- sd(preloaded_data_1$fertilisation_success)

ggplot(preloaded_data_1, aes(x = fertilisation_success)) +
  geom_histogram(aes(y = after_stat(density)), binwidth = 10, boundary = 0,
                 fill = "grey70", colour = "black") +
  stat_function(fun = dnorm, args = list(mean = av, sd = stdev),
                colour = "red", linewidth = 1) +
  labs(x = "Fertilisation success (eggs fertilised per 100)", y = "Density") +
  theme_classic(base_size = 14)
9.1.2.2 Faceting
Often we want the same plot repeated for each group in the data, for example to compare the distribution of the response across treatments. In ggplot2, faceting does this: one extra line of code repeats the plot for every level of a variable. Here we draw one histogram per copper concentration:
ggplot(preloaded_data_1, aes(x = fertilisation_success)) +
  geom_histogram(binwidth = 20, boundary = 0, fill = "grey70", colour = "black") +
  facet_wrap(~ copper_concentration, ncol = 1, labeller = label_both) +
  labs(x = "Fertilisation success (eggs fertilised per 100)", y = "Frequency") +
  theme_classic(base_size = 14)
facet_grid() lays the panels out in a grid by two variables. Here, rows are sperm concentration and columns are copper concentration, so each combination of the experimental treatments gets its own panel:
ggplot(preloaded_data_1, aes(x = fertilisation_success)) +
  geom_histogram(binwidth = 20, boundary = 0, fill = "grey70", colour = "black") +
  facet_grid(sperm_concentration ~ copper_concentration, labeller = label_both) +
  labs(x = "Fertilisation success (eggs fertilised per 100)", y = "Frequency") +
  theme_classic(base_size = 14)
In facet_wrap(~ copper_concentration, ncol = 1), what does ncol = 1 do? How would you get the panels side by side instead?
It puts all the panels in a single column (stacked).
Use
ncol = 2 (or nrow = 1) to put the panels side by side.
9.1.2.3 Combining different plots with patchwork
Faceting repeats the same plot across groups in your data. Sometimes you want to put different plots next to each other in one figure. The patchwork package does this: save each ggplot as an object, and then combine them with + (side by side), or / (stacked).
## Save two different plots as objects
p_counts <- ggplot(preloaded_data_1, aes(x = fertilisation_success)) +
  geom_histogram(binwidth = 10, boundary = 0, fill = "grey70", colour = "black") +
  labs(x = "Fertilisation success", y = "Frequency") +
  theme_classic(base_size = 14)

p_density <- ggplot(preloaded_data_1, aes(x = fertilisation_success)) +
  geom_histogram(aes(y = after_stat(density)), binwidth = 10, boundary = 0,
                 fill = "grey70", colour = "black") +
  stat_function(fun = dnorm, args = list(mean = av, sd = stdev), colour = "red", linewidth = 1) +
  labs(x = "Fertilisation success", y = "Density") +
  theme_classic(base_size = 14)

## Combine them
p_counts + p_density                                  ## Side by side
p_counts / p_density                                  ## Stacked
(p_counts + p_density) + plot_annotation(tag_levels = "A")   ## Add panel labels A and B
When would you use facet_wrap(), and when would you use patchwork?
Use
facet_wrap() (or facet_grid()) to repeat the same plot for each level of a variable in your data.Use
patchwork to combine different plots, for example plots of different variables, or different types of plot, into one figure.
How would you arrange a 3x2 array of graphs (6 graphs) with ggplot2?
With faceting:
facet_wrap(~ variable, nrow = 3, ncol = 2).With patchwork: combine six plots and add
+ plot_layout(nrow = 3, ncol = 2).
9.2 Bar graphs
Bar graphs display the value of a statistic (on the Y-axis) across the levels a qualitative variable, i.e., one consisting of categorical categories (e.g., "Control" versus "Treated", or "A" versus "B" versus "C", etc). The value can be anything; most commonly it is a mean or a count. The statistic is represented by the height of a "bar" placed over the name of the category.
Bar graphs are effective when you want to compare the magnitude of values among different groups, such as the count of individuals in each species of a plant community. In this example, each species name would be on the x-axis and count would be on the y-axis. Bar graphs are also effective for visually emphasizing change over time, for example, the number of plants in a community from year to year. In this example, year would be on the x-axis and the count would be on the y-axis.
9.2.1 Bar graphs in base R
The standard R function for making a bar plot is conveniently called barplot. The following code plots the mean "Fertilization Success" across the two levels of "Sperm concentration", and adds a 95% confidence interval to each mean.
## 1. Calculate the means for each group
## Split data into groups
groups <- split(preloaded_data_1$fertilisation_success, preloaded_data_1$sperm_concentration)

## Calculate the mean for each group
means <- sapply(groups, mean)

## 2. Plotting the means
my.barplot <- barplot(means,          ## Set heights of bars
names.arg = c("High", "Low"),         ## Labels for the X-axis
ylab = "mean Fertilization Success",  ## Title for the Y-axis
xlab = "Sperm concentration",         ## Title for the X-axis
col = c("grey60", "grey90"),          ## Set colours for the bars
ylim = c(0, 90))                      ## Make the Y-axis go to 90

## 3. Add confidence intervals
## Calculate a variance within each group
variance <- tapply(preloaded_data_1$fertilisation_success, preloaded_data_1$sperm_concentration, var)

## Calculate a sample size within each group
n_group <- tapply(preloaded_data_1$fertilisation_success, preloaded_data_1$sperm_concentration, length)

## Convert variance to standard error, within each group
se <- sqrt(variance/n_group)

## Draw each error bar as a "double headed arrow" that has a 90 degree angle between "head" and "stem"
arrows(my.barplot, means - 1.96 * se, my.barplot, means + 1.96 * se, code = 3, angle = 90)
NB: 1.96 standard errors is the approximate 95% confidence interval from the normal distribution. With small samples it is better to use the t-distribution instead, as we do in the line graphs section below.
Notice how much of this code is about calculating the means and error bars by hand. The bars themselves are the easy part.
9.2.2 Bar graphs in ggplot2
In ggplot2, we first calculate the summary statistics in a small data frame, and then plot that data frame. We use dplyr to do the calculating: group_by() splits the data by group, and summarise() calculates a statistic for each group.
fert_summary <- preloaded_data_1 %>%
  group_by(sperm_concentration) %>%
  summarise(mean_success = mean(fertilisation_success),
            se = sd(fertilisation_success) / sqrt(n()),
            lower = mean_success - 1.96 * se,
            upper = mean_success + 1.96 * se)

fert_summary   ## Have a look at the summary table
Now we plot the summary table. geom_col() draws bars whose heights are values in the data (here mean_success), and geom_errorbar() adds the confidence intervals using the lower and upper columns.
ggplot(fert_summary, aes(x = sperm_concentration, y = mean_success)) +
  geom_col(fill = "grey70", colour = "black", width = 0.6) +
  geom_errorbar(aes(ymin = lower, ymax = upper), width = 0.2) +
  scale_y_continuous(expand = expansion(mult = c(0, 0.05))) +   ## Start the bars at the axis, no gap
  labs(x = "Sperm concentration", y = "Mean fertilisation success") +
  theme_classic(base_size = 14)
One strength of ggplot2 is how easily it handles more than one grouping variable. To show the mean for every combination of sperm concentration and copper concentration, we group by both variables in summarise(), and then map copper concentration to the fill of the bars. position_dodge() places the bars side by side instead of on top of each other.
fert_summary2 <- preloaded_data_1 %>%
  group_by(sperm_concentration, copper_concentration) %>%
  summarise(mean_success = mean(fertilisation_success),
            se = sd(fertilisation_success) / sqrt(n()),
            lower = mean_success - 1.96 * se,
            upper = mean_success + 1.96 * se,
            .groups = "drop") %>%
  mutate(copper_concentration = factor(copper_concentration))   ## Treat copper as a category, not a number

ggplot(fert_summary2, aes(x = sperm_concentration, y = mean_success, fill = copper_concentration)) +
  geom_col(position = position_dodge(width = 0.7), width = 0.6, colour = "black") +
  geom_errorbar(aes(ymin = lower, ymax = upper),
                position = position_dodge(width = 0.7), width = 0.2) +
  scale_fill_manual(values = c("grey90", "grey40"), name = "Copper (mg/L)") +
  scale_y_continuous(expand = expansion(mult = c(0, 0.05))) +
  labs(x = "Sperm concentration", y = "Mean fertilisation success") +
  theme_classic(base_size = 14)
NB: scale_fill_manual() lets you choose your own colours. For ready-made colour-blind friendly palettes, try scale_fill_viridis_d().
What does the position_dodge() argument do, and what happens if you remove it from both geom_col() and geom_errorbar()?
It places the bars (and error bars) for each copper level side by side. Without it the bars are stacked on top of each other and the error bars no longer line up.
What information about the data does a bar graph of means with confidence intervals not show?
It hides the raw data: the spread of the individual observations, how many there are, and whether the distribution is skewed or has outliers. Quite different datasets can give the same bar. We will deal with this in the next sections.
9.2.2.1 Bar graphs of counts
Sometimes the bar is simply a count of how many observations fall in each category. To demonstrate, we will use data on bird richness at 150 sites that differ in habitat patch size. The data are in the file: bird_richness_vs_land_use_change_data.csv in the "Data" folder of our CONS7008 R project. We will come back to this dataset in later sections.
In base R, table() counts the observations in each category, and barplot() plots the counts.
site_counts <- table(bird$patch_size)
site_counts                             ## The categories are in alphabetical order!

## Reorder them from smallest to largest patch, and plot
site_counts <- site_counts[c("small", "medium", "large")]
barplot(site_counts, xlab = "Patch size", ylab = "Number of sites", col = "grey70")
In ggplot2, geom_bar() does the counting itself, so we only give it the raw data. Just as in base R, the categories would come out in alphabetical order, so we first tell R the order we want by turning patch_size into a factor with the levels in order.
bird$patch_size <- factor(bird$patch_size, levels = c("small", "medium", "large"))

ggplot(bird, aes(x = patch_size)) +
  geom_bar(fill = "grey70", colour = "black") +
  labs(x = "Patch size", y = "Number of sites") +
  scale_y_continuous(expand = expansion(mult = c(0, 0.05))) +
  theme_classic(base_size = 14)
What is the difference between geom_bar() and geom_col()?
geom_bar() counts the rows in each category for you. geom_col() plots bar heights that are already in your data, such as the means we calculated above.
9.3 Scatter plots
Scatter plots are useful to visualise the relationship between two numeric variables.
A scatterplot is a 2D graph containing many scattered points. You have seen this before when using the pairs() function to visualize the relationships between two variables. Each dot represents a single observation, i.e., it identifies two measurements taken on that observation, by reference to the two axes.
In order to illustrate the idea, we will use the bird data again. Each row is a site, with the number of bird species recorded (bird_richness), a measure of habitat fragmentation (fragmentation), the cover of the invasive weed lantana (lantana_cover), and the size of the habitat patch (patch_size). We loaded these data in the bar graphs section, and put the patch sizes in order. If you have restarted R since then, re-run those two chunks first.
9.3.1 Scatter plots in base R
Run the following code and see a basic scatterplot of bird richness against fragmentation:
Customise the appearance by overriding default settings:
plot(bird$fragmentation, bird$bird_richness,
     xlab = "Habitat fragmentation",
     ylab = "Bird richness (number of species)",
     pch = 16,           ## Solid circles
     col = "grey30",     ## Colour of the points
     bty = "l")          ## Only draw the left and bottom edges of the box
Now categorise the dots by patch size. We make an empty plot first, and then add the points on top:
## Choose a colour for each patch size (colour-blind friendly colours)
cols <- c(small = "#E69F00", medium = "#009E73", large = "#0072B2")

## Make the plot but don't draw any points yet
plot(bird$fragmentation, bird$bird_richness, type = "n", bty = "l",
     xlab = "Habitat fragmentation", ylab = "Bird richness (number of species)")

## Add the points, with the colour of each point chosen by the patch size of its site
points(bird$fragmentation, bird$bird_richness, pch = 16, col = cols[as.character(bird$patch_size)])

## Add a legend
legend("topright", legend = names(cols), col = cols, pch = 16, title = "Patch size", bty = "n")
What does type = "n" do, and why is it useful here?
It sets up the axes and labels but draws nothing. We can then add the points ourselves with
points(), and control exactly how they look.
NB: We have deliberately not added a line of best fit to these graphs. A fitted line comes from a model, and a model is only trustworthy once we have checked that it meets its assumptions. We will add fitted lines in the last section of this prac, after checking model diagnostics.
9.3.2 Scatter plots in ggplot2
In ggplot2, we map the variables to the x and y positions inside aes(), and geom_point() draws a point for each row of the data.
Now let's polish it. Settings that apply to every point, such as size and alpha (transparency, which helps when points overlap), go inside geom_point().
ggplot(bird, aes(x = fragmentation, y = bird_richness)) +
  geom_point(size = 2, alpha = 0.7) +
  labs(x = "Habitat fragmentation", y = "Bird richness (number of species)") +
  theme_classic(base_size = 14)
To categorise the dots by patch size we do not need an empty plot, a loop or a legend command. We simply map the colour to the patch_size variable inside aes(), and ggplot2 chooses the colours and builds the legend for us. We can then choose our own colours with scale_colour_manual().
ggplot(bird, aes(x = fragmentation, y = bird_richness, colour = patch_size)) +
  geom_point(size = 2, alpha = 0.8) +
  scale_colour_manual(values = c(small = "#E69F00", medium = "#009E73", large = "#0072B2"),
                      name = "Patch size") +
  labs(x = "Habitat fragmentation", y = "Bird richness (number of species)") +
  theme_classic(base_size = 14)
What is the difference between geom_point(colour = "red") and aes(colour = patch_size)? What happens if you write geom_point(colour = patch_size)?
geom_point(colour = "red") sets one fixed colour for every point. aes(colour = patch_size) maps a variable in the data to colour, so the colour changes with the data and a legend is added.geom_point(colour = patch_size) gives an error ("object 'patch_size' not found"), because variables in the data can only be used inside aes().
9.3.2.1 Faceting
Colour is not the only way to show groups. With faceting, each group gets its own panel. The panels share the same axes, so they are easy to compare.
ggplot(bird, aes(x = fragmentation, y = bird_richness)) +
  geom_point(size = 2, alpha = 0.8) +
  facet_wrap(~ patch_size) +
  labs(x = "Habitat fragmentation", y = "Bird richness (number of species)") +
  theme_classic(base_size = 14)
When would you use colour to show groups, and when would you use facets?
Colour puts the groups on the same axes so that they can be compared directly, but it gets messy when there are many groups or the points overlap a lot.
Facets keep each group separate and uncluttered, but make direct comparison between groups a bit harder. You can also use both together.
9.3.2.2 Combining plots with patchwork
We can also put plots of different variables side by side. Here we plot richness against fragmentation and richness against lantana cover. plot_layout(guides = "collect") combines the two legends into one, and & applies the theme() setting to both plots.
p_frag <- ggplot(bird, aes(x = fragmentation, y = bird_richness, colour = patch_size)) +
  geom_point(size = 2, alpha = 0.8) +
  scale_colour_manual(values = c(small = "#E69F00", medium = "#009E73", large = "#0072B2"),
                      name = "Patch size") +
  labs(x = "Habitat fragmentation", y = "Bird richness (number of species)") +
  theme_classic(base_size = 14)

p_lantana <- ggplot(bird, aes(x = lantana_cover, y = bird_richness, colour = patch_size)) +
  geom_point(size = 2, alpha = 0.8) +
  scale_colour_manual(values = c(small = "#E69F00", medium = "#009E73", large = "#0072B2"),
                      name = "Patch size") +
  labs(x = "Lantana cover (%)", y = "Bird richness (number of species)") +
  theme_classic(base_size = 14)

p_frag + p_lantana + plot_layout(guides = "collect") & theme(legend.position = "bottom")
9.3.3 Extensions to more than one quantitative variable
A "scatter plot matrix" provides an image of statistical association among several quantitative variables simultaneously. It is a collection of 2D scatter plots; one for each pair of variables.
Using a scatter plot matrix is especially helpful when you have measured many values on a population, and want to visualize the pairwise relationships among measurements. For example, you might imagine measuring many quantitative traits on individuals in a population of plants - say, height, branch number, leaf area, chlorophyll concentration, and root mass. A scatterplot matrix can show you the pairwise relationships of all these variables. A scatterplot matrix also helps you troubleshoot collinearity in your models. In our example, if we want to predict bird richness using fragmentation and lantana cover, we can visualize how collinear those predictors are with each other to avoid the problems associated with collinearity.
The pairs command will generate a scatter plot matrix of the columns we choose. Here we select the three quantitative columns of the bird data.
pairs(bird[, c("bird_richness", "fragmentation", "lantana_cover")]) ## Generate every possible 2D scatterplot among these columnsNB: ggplot2 does not have a scatter plot matrix function built in. If you want a ggplot2 version, the GGally package has one called ggpairs().
Does this collection of 2D plots summarise everything there is to know about the statistical association among these three variables?
No, it only summarises associations between each pair of variables. It tells us nothing about potential 2-way interactions (or more complex interactions).
Which pair of variables shows no clear relationship, and why does that matter if we want to fit a regression of bird richness on both fragmentation and lantana cover?
Fragmentation and lantana cover. The two predictors are uncorrelated (orthogonal), so a model can separate their individual effects on richness without the problems caused by collinearity.
9.4 Jitter plots
A jitter plot is a type of "scatter plot", but for which the X-axis refers to a categorical variable. Jitter plots are powerful visualization tools because they can be used to show how raw data are distributed within each group. This can be helpful for the eye to see the spread and central tendency of the data in each group.
We will use the fertilisation data again. Sometimes the points of a scatter plot crowd over the top of one another at each level of the categorical variable, like this:
plot(preloaded_data_1$copper_concentration, preloaded_data_1$fertilisation_success,
     xlab = "Copper concentration (mg/L)", ylab = "Fertilisation success (eggs fertilised per 100)")
This is not as informative as it could be - there are 36 observations at each copper concentration, but many points sit on top of each other, so it is difficult to see where the central tendency might be.
9.4.1 Jitter plots in base R
The solution is to add a little random horizontal scatter to the points at each level of the categorical variable. In base R we can do this with the jitter() function, which adds a small amount of random noise to the values it is given.
plot(jitter(preloaded_data_1$copper_concentration, amount = 5), preloaded_data_1$fertilisation_success,
     xaxt = "n",           ## Turn off the x-axis labelling
     xlab = "Copper concentration (mg/L)", ylab = "Fertilisation success (eggs fertilised per 100)")
axis(side = 1, at = c(0, 50))   ## Add axis labels at the real copper concentrations
NB: base R also has a function called stripchart() that makes this kind of plot with the method = "jitter" argument. We will move straight to ggplot2 here, where jittering, grouping by several variables and adding summaries are all much easier.
Does the amount of horizontal scatter for each group mean anything?
No, it is just for aesthetics.
Repeat the command many times, you will see that a different plot is created each time.
9.4.2 Jitter plots in ggplot2
The same overplotting happens with geom_point(). Notice that we turn copper_concentration into a factor, because we want ggplot to treat the two copper concentrations as categories, not as a continuous number line. We also turn sperm concentration into a factor with the levels in a sensible order (Low then High).
fert <- preloaded_data_1 %>%
  mutate(copper = factor(copper_concentration),
         sperm = factor(sperm_concentration, levels = c("Low", "High")))

ggplot(fert, aes(x = copper, y = fertilisation_success)) +
  geom_point()
geom_jitter() adds the random scatter. We set width to control how far the points spread sideways, and height = 0 to switch off vertical jitter.
Why do we set height = 0? What would happen if we did not?
The vertical position of each point is a real measurement. Jittering it would move points to the wrong values and misrepresent the data. Horizontal jitter is harmless because the x-axis only holds the group labels.
Every time you run that code the points land in slightly different places. If you want the same plot every time (for example, so your figure is reproducible), fix the random seed inside position_jitter(). Now let's polish the plot:
ggplot(fert, aes(x = copper, y = fertilisation_success)) +
  geom_point(position = position_jitter(width = 0.15, height = 0, seed = 1), size = 2, alpha = 0.7) +
  labs(x = "Copper concentration (mg/L)", y = "Fertilisation success (eggs fertilised per 100)") +
  theme_classic(base_size = 14)
9.4.2.1 Showing more than one grouping variable
The experiment has two treatments: copper concentration and sperm concentration. We can show both by colouring the points by sperm concentration. position_jitterdodge() jitters the points and also moves each colour to its own side of the copper category, so that they do not sit on top of each other.
ggplot(fert, aes(x = copper, y = fertilisation_success, colour = sperm)) +
  geom_point(position = position_jitterdodge(jitter.width = 0.15, jitter.height = 0,
                                             dodge.width = 0.6, seed = 1),
             size = 2, alpha = 0.7) +
  scale_colour_manual(values = c(Low = "#E69F00", High = "#0072B2"), name = "Sperm concentration") +
  labs(x = "Copper concentration (mg/L)", y = "Fertilisation success (eggs fertilised per 100)") +
  theme_classic(base_size = 14)
Faceting is an alternative. Each sperm concentration gets its own panel:
ggplot(fert, aes(x = copper, y = fertilisation_success)) +
  geom_point(position = position_jitter(width = 0.15, height = 0, seed = 1), size = 2, alpha = 0.7) +
  facet_wrap(~ sperm, labeller = label_both) +
  labs(x = "Copper concentration (mg/L)", y = "Fertilisation success (eggs fertilised per 100)") +
  theme_classic(base_size = 14)
9.4.2.2 Adding means and error bars
Finally, we can add the mean and confidence interval of each group on top of the raw data, to summarise how the mean changes from group to group. We calculate the summaries with dplyr (as we did for the bar graphs), and add them as a second layer using geom_pointrange(). The summary layer uses its own data frame, fert_means, so we give it data = fert_means. position_dodge() must use the same dodge.width as the points so that the means line up with the clouds of points.
## 1. Calculate the mean, standard error and 95% interval of each group
fert_means <- fert %>%
  group_by(copper, sperm) %>%
  summarise(mean_success = mean(fertilisation_success),
            se = sd(fertilisation_success) / sqrt(n()),
            lower = mean_success - 1.96 * se,
            upper = mean_success + 1.96 * se,
            .groups = "drop")

## 2. Plot the raw data, and add the means and intervals as a second layer
ggplot(fert, aes(x = copper, y = fertilisation_success, colour = sperm)) +
  geom_point(position = position_jitterdodge(jitter.width = 0.15, jitter.height = 0,
                                             dodge.width = 0.6, seed = 1),
             size = 2, alpha = 0.5) +
  geom_pointrange(data = fert_means,
                  aes(y = mean_success, ymin = lower, ymax = upper, group = sperm),
                  position = position_dodge(width = 0.6), colour = "black", size = 0.8) +
  scale_colour_manual(values = c(Low = "#E69F00", High = "#0072B2"), name = "Sperm concentration") +
  labs(x = "Copper concentration (mg/L)", y = "Fertilisation success (eggs fertilised per 100)") +
  theme_classic(base_size = 14)
What does this plot show that the bar graph of means in the previous section did not?
The raw data. We can see the spread of the individual observations, how many there are, and whether the groups overlap, as well as the mean and its confidence interval.
The confidence intervals look much narrower than the spread of the points. Why?
The confidence interval describes our uncertainty about the mean of each group (it shrinks as the sample size grows), whereas the spread of the points describes the variation among individual observations.
9.5 Line graphs
Line graphs concern the relationship between two quantitative variables. Line graphs are nice when you want to emphasize a trend or pattern through time, such as the increase or decrease of population size through time, or the cycling of population size through time.
A classic example is the change of a mean across values of another variable. The mean is usually displayed with error bars, but beware of the assumptions you make about the distribution of the data when you plot means and error bars!!!
To demonstrate, we will use data from a field experiment on plant biomass that you analysed in the practical on mixed models. The data are in the file: biomassData.csv in the "Data" folder of our CONS7008 R project. The experiment used a randomised block design: there were 6 blocks, and in each block 3 plots were fenced with an enclosure (enclosure = "Y") and 3 plots were left unfenced (enclosure = "N"). The biomass in each of the 36 plots was measured at four sample times (timeSample, 0 to 3). We want to know how biomass changed through time in the two treatments.
library(glmmTMB)   ## For fitting the mixed model. Install it first if needed: install.packages("glmmTMB")
library(emmeans)   ## For estimated means and confidence intervals from a model. Install it first if needed: install.packages("emmeans")
library(DHARMa)    ## For checking the diagnostics of models. Install it first if needed: install.packages("DHARMa")

biomass <- read.csv("Data/biomassData.csv", header = TRUE)

## Tell R which variables are categories
biomass$enclosure <- factor(biomass$enclosure)
biomass$timeF <- factor(biomass$timeSample)    ## Sample time as a category, so we can estimate a mean at each time
biomass$block <- factor(biomass$block)
biomass$plot <- factor(biomass$plot)

head(biomass)
9.5.1 Fitting the model
The same 36 plots were measured four times, so the 144 rows are not 144 independent replicates, and the plots within a block share a similar environment. To plot the means and confidence intervals properly, we must first analyse the data properly. We fit a mixed model with glmmTMB, as in the earlier practical: the fixed effects are enclosure, sample time and their interaction, and there are random intercepts for block (blocks differ from one another) and for plot (repeated measurements on the same plot are correlated).
fit_biomass <- glmmTMB(biomass ~ enclosure * timeF + (1 | block) + (1 | plot), data = biomass)
summary(fit_biomass)
Before we use the model, we check the diagnostics with the DHARMa package, as in the earlier practicals. We will do this for every model in this prac.
sim_biomass <- simulateResiduals(fit_biomass)   ## Simulate residuals from the fitted model
plot(sim_biomass)                               ## Q-Q plot (left) and residuals against predicted values (right)
Are the assumptions of the model reasonably met?
If the points in the Q-Q plot sit close to the line, no tests are flagged as significant (red), and the residuals show no clear pattern against the predicted values, then the assumptions are reasonably met and we can go ahead and use this model.
9.5.2 Estimated means from the model
The emmeans package calculates the estimated marginal mean of the response for each combination of treatments, from the fitted model, along with a confidence interval that takes the structure of the model into account (the blocks and the repeated measurements). The formula ~ enclosure | timeF asks for the mean of each enclosure treatment at each sample time.
emm <- emmeans(fit_biomass, ~ enclosure | timeF)
emm_df <- as.data.frame(emm)     ## Turn the results into a data frame

## Rename the confidence limit columns so the code below is simple
names(emm_df)[names(emm_df) %in% c("lower.CL", "asymp.LCL")] <- "lower"
names(emm_df)[names(emm_df) %in% c("upper.CL", "asymp.UCL")] <- "upper"

## Turn the sample time back into a number for the x-axis
emm_df$timeSample <- as.numeric(as.character(emm_df$timeF))

emm_df    ## Have a look at the results
Why do these confidence intervals differ from the ones we would get by calculating the standard error of the raw data at each time?
The raw standard errors treat all the plots as independent and ignore the block structure. The model-based intervals account for the variation among blocks and for the repeated measurements on each plot, and they use all the data to estimate the variation.
9.5.3 Line graphs in base R
Now draw the line graph from the estimated means, with the raw data behind them. We shift the two treatments slightly apart on the x-axis (by 0.03) so that the points and error bars do not overlap. We set up the axes first (type = "n" draws nothing), then add the raw data, and then the means on top. The y-axis must cover the raw data as well as the intervals.
## Pull out the rows for each treatment
enclosed <- emm_df[emm_df$enclosure == "Y", ]
unfenced <- emm_df[emm_df$enclosure == "N", ]
raw_enclosed <- biomass[biomass$enclosure == "Y", ]
raw_unfenced <- biomass[biomass$enclosure == "N", ]

## Set up the axes without drawing anything yet
plot(emm_df$timeSample, emm_df$emmean, type = "n",
     ylim = range(biomass$biomass, emm_df$lower, emm_df$upper),
     xlab = "Sample time", ylab = "Biomass")

## Add the raw data as faint points (adjustcolor makes a colour partly transparent)
points(raw_enclosed$timeSample - 0.03, raw_enclosed$biomass, pch = 16, col = adjustcolor("blue", alpha.f = 0.25))
points(raw_unfenced$timeSample + 0.03, raw_unfenced$biomass, pch = 1, col = adjustcolor("red", alpha.f = 0.25))

## Add the estimated means, joined by lines, for each treatment
points(enclosed$timeSample - 0.03, enclosed$emmean, type = "b", pch = 16, col = "blue")
points(unfenced$timeSample + 0.03, unfenced$emmean, type = "b", pch = 1, col = "red")

## Add error bars to the means appearing on the graph
arrows(enclosed$timeSample - 0.03, enclosed$lower, enclosed$timeSample - 0.03, enclosed$upper,
       length = 0.05, angle = 90, code = 3, col = "blue")
arrows(unfenced$timeSample + 0.03, unfenced$lower, unfenced$timeSample + 0.03, unfenced$upper,
       length = 0.05, angle = 90, code = 3, col = "red")

## Add a legend
legend("topleft",                         ## Position for the legend
       legend = c("Y", "N"),              ## Legend labels
       title = "Enclosure",               ## Legend title
       col = c("blue", "red"),            ## Colour of points and lines
       pch = c(16, 1),                    ## Point type
       lty = 1,                           ## Line type
       bty = "n"                          ## No box around the legend
)
Which part of the code causes the lines to be drawn that connect the means?
type = "b"
The graph has a box around it. How would you modify the graph to remove the box?
bty = "n" (no box at all), or bty = "l" to keep just the left and bottom axes.
What is the difference between a line graph and a scatter plot?
Scatter plots show the raw data.
Line graphs display a summary of the raw data.
9.5.4 Line graphs in ggplot2
In ggplot2, the data frame of estimated means is already in the tidy form that ggplot likes, with one row for each point on the graph. We draw the lines (geom_line()) and the points with their confidence intervals (geom_pointrange()). Mapping colour to enclosure gives one coloured line per treatment, and a legend. Because the two treatments have similar means at the same time points, we use position_dodge() to shift them slightly apart so that the intervals do not overlap.
pd <- position_dodge(width = 0.1)    ## Shift each treatment a small amount sideways

ggplot(emm_df, aes(x = timeSample, y = emmean, colour = enclosure)) +
  geom_line(position = pd) +
  geom_pointrange(aes(ymin = lower, ymax = upper), position = pd) +
  scale_colour_manual(values = c(Y = "#0072B2", N = "#D55E00"), name = "Enclosure") +
  scale_x_continuous(breaks = 0:3) +
  labs(x = "Sample time", y = "Mean biomass") +
  theme_classic(base_size = 14)
As with models earlier in this prac, it is good practice to show the raw data behind the model. Here, we add a faint line for each plot, so we can see the individual trajectories. The raw data come from a different data frame (biomass), so we give that layer its own data and aes().
ggplot(emm_df, aes(x = timeSample, y = emmean, colour = enclosure)) +
  geom_line(data = biomass, aes(x = timeSample, y = biomass, group = plot, colour = enclosure),
            alpha = 0.25, inherit.aes = FALSE) +
  geom_line(position = pd, linewidth = 1) +
  geom_pointrange(aes(ymin = lower, ymax = upper), position = pd) +
  scale_colour_manual(values = c(Y = "#0072B2", N = "#D55E00"), name = "Enclosure") +
  scale_x_continuous(breaks = 0:3) +
  labs(x = "Sample time", y = "Biomass") +
  theme_classic(base_size = 14)
What does the graph suggest about the effect of the enclosure through time?
Biomass increases through time in both treatments, but more steeply in the enclosed plots. The two treatments are similar at the start (the confidence intervals overlap at sample time 0) and then diverge, with higher biomass in the enclosed plots at later sample times.
Two confidence intervals overlap at one of the sample times. Does that mean the enclosure has no effect at that time?
Not necessarily. The intervals for the individual means include the variation among blocks, but the treatments were compared within blocks, which makes the comparison between them more precise. To test the difference between treatments properly we compare them directly (for example with
pairs(emm)), rather than judging by whether the intervals overlap.
9.6 Plotting from models
In the line graphs section we plotted the estimated means from a mixed model for a categorical explanatory variable (enclosure), at a handful of sample times. Here we turn to continuous explanatory variables, where the model predicts a line or a curve. The best way to communicate the results of a model is to plot what the model predicts: the fitted relationship between the response and an explanatory variable, with the other explanatory variables held constant, and a measure of our uncertainty. Wherever possible, we also show the raw data behind the model.
Two rules apply every time you plot from a model:
- Check the model's diagnostics first. A beautiful plot of an inappropriate model is misleading.
- Plot the raw data as well as the predictions where you can, so readers can see how well the model describes the data.
We will use three datasets. The first is the bird data you have seen before. The second is a survey of beetles: beetle_data.csv has the number of beetles caught at 150 sites (counts), the maximum temperature at each site (Tmax, °C) and the distance of the site from the forest edge (dist_to_edge, m). The third, a survey of plants in bushland reserves, is introduced at the end of this section.
library(ggeffects)   ## For predict_response(). Install it first if needed: install.packages("ggeffects")

## The bird data are already loaded, from the bar graphs section (re-run those chunks if you have restarted R)

## Read in the beetle data
beetle <- read.csv("Data/beetle_data.csv", header = TRUE)

## Colours for the three patch sizes
patch_cols <- c(small = "#E69F00", medium = "#009E73", large = "#0072B2")
9.6.1 A linear model with a continuous and a categorical predictor
First, we fit a linear model of bird richness as a function of fragmentation, lantana cover and patch size. This model has no interactions, so the effect of fragmentation is the same for each patch size, but patches of different sizes can have different average richness.
Before we plot anything, we check the diagnostics:
Are the assumptions of the linear model reasonably met?
Yes. The points in the Q-Q plot sit close to the line, no tests are flagged as significant, and there is no clear pattern in the residuals against the predicted values. We can go ahead and plot from this model.
9.6.1.1 Predictions in base R
In base R, we can draw a line from the model by writing out its equation, using the coefficients from the model. The curve() function draws the line. We show the effect of fragmentation on richness at the average lantana cover. Because there are three patch sizes, we need three lines, and we must add the coefficient for each patch size by hand:
b <- coef(fit_bird)                                ## Extract the coefficients
b                                                  ## Have a look at them
lantana_mean <- mean(bird$lantana_cover)           ## Hold lantana cover at its average

## Plot the raw data, coloured by patch size
plot(bird$fragmentation, bird$bird_richness, pch = 16, col = patch_cols[as.character(bird$patch_size)],
     bty = "l", xlab = "Habitat fragmentation", ylab = "Bird richness (number of species)")

## Add one line for each patch size
curve(b["(Intercept)"] + b["fragmentation"] * x + b["lantana_cover"] * lantana_mean,
      add = TRUE, col = patch_cols["small"], lwd = 2)
curve(b["(Intercept)"] + b["patch_sizemedium"] + b["fragmentation"] * x + b["lantana_cover"] * lantana_mean,
      add = TRUE, col = patch_cols["medium"], lwd = 2)
curve(b["(Intercept)"] + b["patch_sizelarge"] + b["fragmentation"] * x + b["lantana_cover"] * lantana_mean,
      add = TRUE, col = patch_cols["large"], lwd = 2)

legend("topright", legend = names(patch_cols), col = patch_cols, pch = 16, lty = 1,
       title = "Patch size", bty = "n")
This works, but it is a lot of bookkeeping, and there are no confidence intervals. Every extra predictor or interaction would make the equations longer.
9.6.1.2 Predictions with ggeffects and ggplot2
The predict_response() function from the ggeffects package does the bookkeeping for us. We tell it the model, and the explanatory variables (terms) we want on the plot. The first term goes on the x-axis, and the second term defines the groups. All the other explanatory variables are held at typical values (see ?predict_response).
pred_frag <- predict_response(fit_bird, terms = c("fragmentation", "patch_size"))
head(as.data.frame(pred_frag))   ## Have a look at what it returns
What do the columns x, predicted, conf.low, conf.high and group contain?
x is the value of the first term (fragmentation), predicted is the model's predicted mean richness at that value, conf.low and conf.high are the limits of the 95% confidence interval for that mean, and group is the level of the second term (patch size).
predict_response() returns a data frame, so we can plot it with ggplot2 just like any other data. geom_line() draws the predictions, geom_ribbon() draws the confidence interval as a shaded band, and geom_point() adds the raw data.
ggplot(pred_frag, aes(x = x, y = predicted, colour = group, fill = group)) +
  geom_point(data = bird, aes(x = fragmentation, y = bird_richness, colour = patch_size),
             inherit.aes = FALSE, alpha = 0.5, size = 2) +
  geom_ribbon(aes(ymin = conf.low, ymax = conf.high), alpha = 0.2, colour = NA) +
  geom_line(linewidth = 1) +
  scale_colour_manual(values = patch_cols, name = "Patch size") +
  scale_fill_manual(values = patch_cols, name = "Patch size") +
  labs(x = "Habitat fragmentation", y = "Bird richness (number of species)") +
  theme_classic(base_size = 14)
NB: The shaded bands are 95% confidence intervals for the mean richness (the fitted line), not prediction intervals for individual sites. That is why most of the points lie outside the bands.
NB: ggeffects also has a plot() function for a quick look: try plot(pred_frag).
With only three groups, faceting can make the figure easier to read. We copy group into a column called patch_size, so that the predictions and the raw data share a column that we can facet by:
pred_df <- as.data.frame(pred_frag) %>%
  mutate(patch_size = group)

ggplot(pred_df, aes(x = x, y = predicted)) +
  geom_point(data = bird, aes(x = fragmentation, y = bird_richness), colour = "grey60", alpha = 0.7, size = 2) +
  geom_ribbon(aes(ymin = conf.low, ymax = conf.high), alpha = 0.3) +
  geom_line(linewidth = 1) +
  facet_wrap(~ patch_size) +
  labs(x = "Habitat fragmentation", y = "Bird richness (number of species)") +
  theme_classic(base_size = 14)
The three lines are parallel. Why?
Because the model has no interaction between fragmentation and patch size. It assumes the effect of fragmentation (the slope) is the same in every patch size, and patch size only shifts the line up or down.
9.6.2 A linear model with an interaction
Now we fit a model with an interaction between the two continuous predictors, fragmentation and lantana cover. This lets the effect of fragmentation on richness depend on how much lantana there is. Again, we check the diagnostics before we plot:
fit_int <- lm(bird_richness ~ fragmentation * lantana_cover, data = bird)

plot(simulateResiduals(fit_int))
To show an interaction between two continuous variables we need to choose a few values of the second variable and draw one line for each. We can give values in square brackets after the name of the term. Here we show the effect of fragmentation at lantana covers of 20%, 30% and 40%.
pred_int <- predict_response(fit_int, terms = c("fragmentation", "lantana_cover [20, 30, 40]"))

p_int <- ggplot(pred_int, aes(x = x, y = predicted, colour = group, fill = group)) +
  geom_point(data = bird, aes(x = fragmentation, y = bird_richness), inherit.aes = FALSE,
             colour = "grey60", alpha = 0.6, size = 2) +
  geom_ribbon(aes(ymin = conf.low, ymax = conf.high), alpha = 0.15, colour = NA) +
  geom_line(linewidth = 1) +
  scale_colour_viridis_d(name = "Lantana cover (%)", end = 0.85) +
  scale_fill_viridis_d(name = "Lantana cover (%)", end = 0.85) +
  labs(x = "Habitat fragmentation", y = "Predicted bird richness") +
  theme_classic(base_size = 14)

p_int
What does the plot tell you about how the effect of fragmentation on richness depends on lantana cover?
The lines are not parallel. Richness falls with fragmentation at every level of lantana cover, but the decline is steepest where lantana cover is low and shallower where lantana cover is high. The effect of fragmentation depends on the level of lantana, which is what a significant interaction means.
9.6.3 A generalised linear model (GLM)
Beetle counts are not normally distributed, so we use a Poisson GLM, which models the log of the expected count. We fit it with glm() and family = poisson.
As always, check the diagnostics first. For a Poisson model, we also test for overdispersion (more variation than a Poisson distribution allows).
sim_beetle <- simulateResiduals(fit_beetle)
plot(sim_beetle)
testDispersion(sim_beetle)    ## A formal test for overdispersion
What would a dispersion value well above 1 (with a significant test) tell us, and is it a problem here?
It would mean the counts vary more than a Poisson model expects, so the model's standard errors and confidence intervals would be too small. Here the dispersion is close to 1 (only slightly above), so the Poisson model is a reasonable choice.
9.6.3.1 Predictions in base R
The coefficients of a Poisson GLM are on the log scale. To draw the predicted counts in base R we must back-transform the equation with exp(). Here we draw the effect of distance to the forest edge at the average temperature:
b <- coef(fit_beetle)

plot(beetle$dist_to_edge, beetle$counts, pch = 16, col = "grey60", bty = "l",
     xlab = "Distance to forest edge (m)", ylab = "Number of beetles")

curve(exp(b["(Intercept)"] + b["Tmax"] * mean(beetle$Tmax) + b["dist_to_edge"] * x),
      add = TRUE, col = "red", lwd = 2)
Why do we need exp(), and why is the line curved, when the model equation on the log scale is a straight line?
The model is a straight line on the log scale, but counts are on the original scale.
exp() back-transforms the predictions to counts. On the count scale each extra metre multiplies the expected count by the same factor, rather than adding the same amount, which gives a curve.
9.6.3.2 Predictions with ggeffects and ggplot2
predict_response() handles the back-transformation automatically: the predictions it returns are already on the scale of the counts, and so are the confidence intervals. We show the effect of distance to the forest edge at three temperatures:
pred_beetle <- predict_response(fit_beetle, terms = c("dist_to_edge", "Tmax [26, 28, 30]"))

p_beetle <- ggplot(pred_beetle, aes(x = x, y = predicted, colour = group, fill = group)) +
  geom_point(data = beetle, aes(x = dist_to_edge, y = counts), inherit.aes = FALSE,
             colour = "grey60", alpha = 0.6, size = 2) +
  geom_ribbon(aes(ymin = conf.low, ymax = conf.high), alpha = 0.15, colour = NA) +
  geom_line(linewidth = 1) +
  scale_colour_viridis_d(name = "Tmax (°C)", end = 0.85) +
  scale_fill_viridis_d(name = "Tmax (°C)", end = 0.85) +
  labs(x = "Distance to forest edge (m)", y = "Predicted number of beetles") +
  theme_classic(base_size = 14)

p_beetle
What does the plot tell you about the effects of temperature and distance to the forest edge on beetle counts?
Beetle counts increase with distance from the forest edge, and are lower at higher temperatures. The lines for the three temperatures have the same shape and are simply shifted, because the model has no interaction between temperature and distance.
NB: In these two plots the grey points are all the sites, whatever their lantana cover or temperature, whereas each line shows the model's prediction for one value of the other explanatory variable. The lines will not pass through the middle of the points at every x.
9.6.4 A generalised linear mixed model (GLMM)
Our last example is a survey of plants in bushland reserves in south-western Western Australia. The data are in plant_quadrat_data.csv. The design is nested: in each of 16 reserves, 4 plots were established, and in each plot the number of plant species was counted in 5 quadrats, giving 320 quadrats in all. Two explanatory variables were recorded:
rainfall_mm, the mean annual rainfall of the reserve (one value per reserve)soil_P, the soil phosphorus concentration (mg/kg) measured in each quadrat
The response, species_count, is the number of plant species in the quadrat. The south-western Australian flora is extraordinarily diverse on old, nutrient-poor soils, and species richness is expected to fall as soil phosphorus rises.
plants <- read.csv("Data/plant_quadrat_data.csv", header = TRUE)
plants$reserve <- factor(plants$reserve)
plants$rain100 <- plants$rainfall_mm / 100    ## Rainfall in units of 100 mm, so that a "one unit" change is meaningful

head(plants)
Plots are numbered 1 to 4 and quadrats 1 to 5, and the same numbers are used in every reserve. How does the model formula (1 | reserve/plot) deal with this?
The
/ tells glmmTMB that plot is nested within reserve, so plot 1 in reserve R01 is a different plot from plot 1 in reserve R02. The formula is shorthand for (1 | reserve) + (1 | reserve:plot). If we wrote (1 | reserve) + (1 | plot), R would treat all the plots numbered 1 as one plot, which is wrong.
9.6.4.1 Fitting and checking the model
The counts are small whole numbers, so we model them with a negative binomial distribution (family = nbinom2), which is like a Poisson distribution that allows more variation than the mean. The model has a random intercept for each reserve, and for each plot within each reserve, to account for the spatial nesting. We put log10() around soil phosphorus inside the model formula, because phosphorus is right-skewed and we expect changes in phosphorus to act multiplicatively (going from 2 to 4 mg/kg should matter as much as going from 8 to 16).
fit_plants <- glmmTMB(species_count ~ rain100 + log10(soil_P) + (1 | reserve/plot),
                      family = nbinom2, data = plants)
summary(fit_plants)
Rainfall and soil phosphorus both have effects in the summary. How would you describe the size of each effect on the count?
The coefficients are on the log scale, so
exp() of a coefficient is the multiplier on the expected count. For rainfall, the coefficient is per 100 mm, so exp(coefficient) is the multiplier for each extra 100 mm of rainfall (roughly +10%). For soil phosphorus, the coefficient is per 10-fold increase (because we used log10), so exp(coefficient) is the multiplier for a 10-fold increase in phosphorus (roughly halving the expected count).
Before we plot, we check the diagnostics with DHARMa. If the model fits well, the points in the left panel fall along the line, and there are no significant patterns in the right panel. We also test for overdispersion.
sim_res <- simulateResiduals(fit_plants)
plot(sim_res)
testDispersion(sim_res)    ## A non-significant result is what we want
Are the assumptions of the model reasonably met?
Check your own plots. The simulated residuals should follow the line in the Q-Q plot, there should be no significant deviation or dispersion problem, and no clear pattern when residuals are plotted against the predicted values. If so, we can go ahead and plot from this model.
9.6.4.2 Predictions in base R
In base R we can draw the fitted curve by extracting the fixed effect coefficients with fixef(), back-transforming with exp(). Here we show the effect of soil phosphorus at the average rainfall. This line is for a "typical" reserve and plot, because we ignore the random effects.
b <- fixef(fit_plants)$cond    ## Coefficients of the fixed effects

plot(plants$soil_P, plants$species_count, pch = 16, col = adjustcolor("grey40", alpha.f = 0.4), bty = "l",
     xlab = "Soil phosphorus (mg/kg)", ylab = "Number of plant species per quadrat")

curve(exp(b["(Intercept)"] + b["rain100"] * mean(plants$rain100) + b["log10(soil_P)"] * log10(x)),
      add = TRUE, col = "red", lwd = 2)
Why does the code use log10(x) inside curve()?
Because the model was fitted to
log10(soil_P), the coefficient applies to the log10 of phosphorus, not to phosphorus itself. To predict at a particular concentration (x), we must transform it in the same way as the model did.
9.6.4.3 Predictions with ggeffects and ggplot2
The predict_response() function does this bookkeeping for us, even for a mixed model. You give it the name of the variable as it appears in your data (soil_P, not log10(soil_P)), and the values you want in the original units (mg/kg), and it applies the log10() for you. Here [0.5:28 by = 0.1] asks for predictions from 0.5 to 28 mg/kg in steps of 0.1, which is fine enough to draw a smooth curve. The predictions are counts. The line and band are for a typical reserve and plot (the random effects are set to zero).
pred_rain <- predict_response(fit_plants, terms = "rain100")
pred_P <- predict_response(fit_plants, terms = "soil_P [0.5:28 by = 0.1]")

head(as.data.frame(pred_P))   ## x is in mg/kg and predicted is in numbers of species
Now we plot each prediction over the raw data. Rainfall was measured once per reserve, so there are only 16 independent values of rainfall. We show all of the quadrats as faint points (the 20 quadrats in each reserve line up vertically), and the mean of each reserve as a solid point.
reserve_means <- plants %>%
  group_by(reserve, rain100) %>%
  summarise(mean_count = mean(species_count), .groups = "drop")

p_rain <- ggplot(pred_rain, aes(x = x, y = predicted)) +
  geom_point(data = plants, aes(x = rain100, y = species_count), inherit.aes = FALSE,
             colour = "grey60", alpha = 0.4, size = 1.5) +
  geom_point(data = reserve_means, aes(x = rain100, y = mean_count), inherit.aes = FALSE,
             colour = "grey20", size = 2.5) +
  geom_ribbon(aes(ymin = conf.low, ymax = conf.high), alpha = 0.25) +
  geom_line(linewidth = 1) +
  labs(x = "Mean annual rainfall (100 mm)", y = "Number of plant species per quadrat") +
  theme_classic(base_size = 14)

p_P <- ggplot(pred_P, aes(x = x, y = predicted)) +
  geom_point(data = plants, aes(x = soil_P, y = species_count), inherit.aes = FALSE,
             colour = "grey60", alpha = 0.6, size = 1.5) +
  geom_ribbon(aes(ymin = conf.low, ymax = conf.high), alpha = 0.25) +
  geom_line(linewidth = 1) +
  labs(x = "Soil phosphorus (mg/kg)", y = "Number of plant species per quadrat") +
  theme_classic(base_size = 14)

p_rain + p_P + plot_annotation(tag_levels = "A")
Both fitted lines are curved, even though the model is a straight line on the log scale. Why? And why does the soil phosphorus curve have the shape it does?
The model is linear on the log scale (the link scale), but the plot is on the count scale. Back-transforming with
exp() turns a straight line into a curve, so any effect in a log-link model will be curved on the response scale, whatever the predictor. (The rainfall curve is a gentle exponential.) The log10() of phosphorus changes the shape further: a given proportional change in phosphorus has the same effect on the count, so the curve drops steeply at low phosphorus, where a 1 mg/kg change is a large proportional change, and flattens at high phosphorus, where it is a small one.
How many independent replicates does the rainfall effect have, and what does that mean for the width of the band in panel A?
Only 16, one for each reserve, even though there are 320 quadrats. Rainfall is a property of the reserve, so quadrats in the same reserve are not independent replicates for the rainfall effect. The random intercept for reserve accounts for this, which is why the band for rainfall is wide relative to the amount of data. Soil phosphorus varies among quadrats within plots, so it is estimated more precisely.
NB: The bands show the uncertainty in the average (fitted) relationship, for a typical reserve and plot. Individual quadrats differ from this because of differences among reserves, plots and quadrats, which is why many points lie outside the band.
9.6.5 Combining figures
Finally, we can use patchwork to combine the model plots into a single figure for a report, with panel labels:
If you wanted to save this figure as a file for a report, what function could you use?
ggsave("my_figure.png", width = 8, height = 4, dpi = 300) saves the last plot you drew. You can also give it a plot object, for example ggsave("my_figure.png", plot = my_plot).
9.7 Try it yourself
These tasks use the bird data again, with the bird data frame and the patch_cols colours from earlier in the prac (re-run those chunks if you need to). For each task, write your own code by adapting an example from earlier in the prac. The hints say where to look. Tasks 1 to 3 are core tasks. Tasks 4 and 5 are stretch tasks. Open the box under each task only after you have had a go.
Remember: every figure needs clear axis labels with units, and no plot titles (describe the figure in a caption instead).
9.7.1 Task 1: A histogram for each patch size
Make a histogram of bird_richness with one panel for each patch size. Choose a sensible bin width. Which patch size tends to have the highest richness?
Hint: look at the histograms and faceting examples.
Show one way to do it
ggplot(bird, aes(x = bird_richness)) +
  geom_histogram(binwidth = 2, fill = "grey70", colour = "white") +
  facet_wrap(~ patch_size, ncol = 1) +      ## One column of panels, so the x-axes line up for comparison
  labs(x = "Bird richness (number of species)", y = "Number of sites") +
theme_classic(base_size = 14)9.7.2 Task 2: Richness against lantana cover
Make a scatter plot of bird_richness (y-axis) against lantana_cover (x-axis), with the points coloured by patch_size using patch_cols. Describe the relationship.
Hint: look at the scatter plot examples, and at how patch_cols was used in the bar graphs and model plots.
Show one way to do it
p_scatter <- ggplot(bird, aes(x = lantana_cover, y = bird_richness, colour = patch_size)) +
  geom_point(size = 2, alpha = 0.7) +
  scale_colour_manual(values = patch_cols, name = "Patch size") +
  labs(x = "Lantana cover (%)", y = "Bird richness (number of species)") +
  theme_classic(base_size = 14)

p_scatter9.7.3 Task 3: Richness by patch size, with means and intervals
Make a plot of bird_richness for each patch_size that shows the raw data as jittered points, and the mean and 95% confidence interval of each group on top.
Hint: look at the jitter plots section, "Adding means and error bars".
Show one way to do it
## 1. Calculate the mean and 95% confidence interval of each group
bird_means <- bird %>%
  group_by(patch_size) %>%
  summarise(mean_richness = mean(bird_richness),
            se = sd(bird_richness) / sqrt(n()),
            lower = mean_richness - qt(0.975, n() - 1) * se,
            upper = mean_richness + qt(0.975, n() - 1) * se)

## 2. Plot the raw data, then add the means and intervals as a second layer
p_jitter <- ggplot(bird, aes(x = patch_size, y = bird_richness)) +
  geom_jitter(width = 0.15, height = 0, alpha = 0.5, colour = "grey50") +
  geom_pointrange(data = bird_means, aes(y = mean_richness, ymin = lower, ymax = upper), size = 0.8) +
  labs(x = "Patch size", y = "Bird richness (number of species)") +
  theme_classic(base_size = 14)

p_jitterheight = 0 in geom_jitter() matters: richness is a count, and jittering vertically would change the values we are showing.
9.7.4 Task 4 (stretch): Plot a model
Fit a linear model of bird_richness as a function of lantana_cover and fragmentation (no interaction). Check the diagnostics before you plot. Then plot the effect of lantana cover on richness at three values of fragmentation, with the confidence bands, over the raw data.
Hint: look at the "linear model with an interaction" example. To choose three values of fragmentation, you can write them in square brackets as before, or look in ?predict_response for a shortcut such as [meansd].
Show one way to do it
fit_ex <- lm(bird_richness ~ lantana_cover + fragmentation, data = bird)

## Diagnostics first
plot(simulateResiduals(fit_ex))

## Then predict and plot
pred_ex <- predict_response(fit_ex, terms = c("lantana_cover", "fragmentation [meansd]"))

ggplot(pred_ex, aes(x = x, y = predicted, colour = group, fill = group)) +
  geom_point(data = bird, aes(x = lantana_cover, y = bird_richness), inherit.aes = FALSE,
             colour = "grey60", alpha = 0.6, size = 2) +
  geom_ribbon(aes(ymin = conf.low, ymax = conf.high), alpha = 0.15, colour = NA) +
  geom_line(linewidth = 1) +
  scale_colour_viridis_d(name = "Fragmentation", end = 0.85) +
  scale_fill_viridis_d(name = "Fragmentation", end = 0.85) +
  labs(x = "Lantana cover (%)", y = "Predicted bird richness") +
theme_classic(base_size = 14)9.7.5 Task 5 (stretch): A two-panel figure
Combine the plots from Tasks 2 and 3 into one figure with panels labelled A and B, and save it as a file that is 9 inches wide and 4 inches tall, at 300 dpi.
Hint: look at the "Combining plots with patchwork" example, and at ggsave().
Show one way to do it
p_scatter + p_jitter + plot_annotation(tag_levels = "A")

ggsave("bird_figure.png", width = 9, height = 4, dpi = 300)
ggsave() saves the last plot that was drawn, so run it straight after drawing the combined figure. The file appears in your working directory.
9.8 List of useful functions
Here are a few useful functions that you learned today.
Base R graphics
hist; barplot; plot; points; lines; curve; arrows; legend; pairs; jitter; adjustcolor; par; axis
Summarising data
tapply; group_by; summarise; mutate; %>%
ggplot2: plots and layers
ggplot; aes; geom_histogram; geom_col; geom_bar; geom_point; geom_jitter; geom_line; geom_errorbar; geom_pointrange; geom_ribbon; stat_function
ggplot2: appearance, panels and scales
labs; theme_classic; theme; facet_wrap; facet_grid; scale_colour_manual; scale_fill_manual; scale_colour_viridis_d; scale_x_continuous; position_dodge; position_jitter; position_jitterdodge; ggsave
patchwork
plot_annotation; plot_layout
Models and predictions
lm; glm; glmmTMB; fixef; emmeans; simulateResiduals and testDispersion (DHARMa); predict_response (ggeffects)
Distributions
dnorm; sd; mean